


Open to Senior SDET, QA Automation Lead and AI Quality Engineering roles.
Gurugram · Bangalore · Hyderabad · remote-friendly
$ cat aayush.spec.yml
role:        Senior SDET & Automation Architect @ Keywords Studios
experience:  4+ years, leading QA across multiple products at once
domains:     [gaming, banking, healthcare, e-commerce, logistics]
education:   MSc Data Science, BSc Computer Science

what_i_do:
  - architect test automation frameworks for web, API and mobile
  - wire quality gates into CI/CD so regressions never reach main
  - test LLM apps, RAG pipelines and AI agents like any other critical system
  - run QA as a lead: test strategy, plans, reporting and release sign-off

building_now:
  - one framework that runs UI, API and mobile suites from a single pipeline
  - a microservices test automation framework
  - LLM evaluation suites that fail the build when answers drift

ask_me_about: [Playwright, Selenium, RestAssured, Postman/Newman, DeepEval, Playwright MCP]
🧪 Featured work
🧰 Automation Arsenal
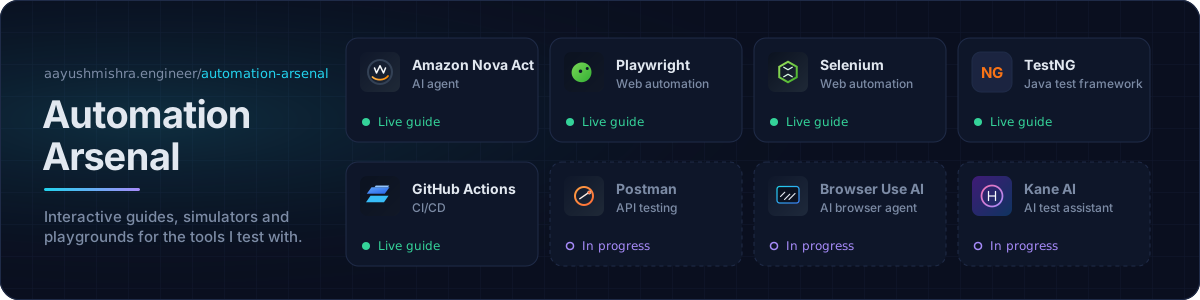
Hands-on guides I built for the tools I use every day. Each one has runnable examples and an interactive simulator or playground, not just notes.
| Guide | What's inside |
|---|---|
| Amazon Nova Act | How AI browser agents think, an agent playground, and how I built my Nova Act test framework |
| Playwright | The commands you'll actually use, an honest comparison with other tools, and a run-it-now demo |
| Selenium WebDriver | How WebDriver works under the hood, Page Object Model, and a browser automation simulator |
| TestNG + Java Selenium | Annotations decoded, how the stack fits together, and an interactive test runner |
| GitHub Actions CI/CD | A six-stage pipeline, trigger types, and a pipeline builder wired to real repos |
Coming next: Postman, Browser Use AI and Kane AI.
🧠 AI quality engineering
AI features don't fail like normal code. The same prompt can pass today and hallucinate tomorrow, so I treat model output, retrieval quality and agent behaviour as things to measure and gate, not eyeball. My Amazon Nova Act agent framework runs end-to-end UI scenarios written in plain English.
flowchart LR
    subgraph AGENTS["AI-assisted automation"]
        A["Test intent<br/>in plain English"] --> B["Playwright MCP<br/>planner · generator · healer"]
        B --> C["Playwright suites<br/>UI + API"]
    end
    subgraph EVALS["Testing the AI itself"]
        D["LLM / RAG app"] --> E["DeepEval<br/>pytest-style LLM evals"]
        D --> F["Ragas<br/>retrieval metrics"]
        D --> G["Promptfoo<br/>red-teaming"]
    end
    C --> H{"CI quality gate<br/>GitHub Actions / Jenkins"}
    E --> H
    F --> H
    G --> H
    H -- pass --> I["🚀 Ship"]
    H -- fail --> J["🔍 Trace, report, fix"]
| Layer | Tools | What it checks |
|---|---|---|
| Agentic UI testing | Playwright MCP, Playwright Test Agents, Amazon Nova Act, Browser-Use | Agents explore the live app, draft test plans, generate specs and repair broken locators |
| LLM output evals | DeepEval (G-Eval, hallucination, answer relevancy) | Pytest-style assertions on model responses, with pass/fail thresholds in CI |
| RAG evaluation | Ragas | Faithfulness, context precision and context recall, so you know whether retrieval or generation is the weak link |
| Red-teaming & prompt regression | Promptfoo | Prompt injection, jailbreaks and PII leaks, plus side-by-side comparison of prompt versions |
| MCP servers & agents | MCP Inspector, tool-call assertions | Tool schemas, tool-call accuracy and whether the agent actually reached its goal |
| Observability | Langfuse, Arize Phoenix | Production traces that feed real failures back into the eval dataset |


🛡️ Testing across the stack
| Area | What I cover | Tools |
|---|---|---|
| UI & end-to-end | Page Object Model, cross-browser runs, parallel execution, retries, screenshots and traces on failure | Playwright, Selenium |
| API & microservices | Schema validation, auth flows, chained requests, data-driven suites, environment configs | RestAssured, Playwright API, Postman + Newman |
| Mobile | Native and hybrid app flows | Appium |
| BDD | Business-readable scenarios that product owners can review | Cucumber, TestNG |
| Performance | Load and stress tests with pass/fail thresholds | JMeter, k6 |
| Security | OWASP Top 10 checks, HTTP security-header audits, reproducible bug reports | Browser DevTools, Postman |
| CI/CD & infra | Pipelines that gate merges, containerised test runs, cloud test infrastructure | GitHub Actions, Jenkins, Docker, AWS, Azure |
| Reporting & management | Allure dashboards, traceable test cases, plans and release reports | Allure, JIRA, Zephyr, TestRail |
| Process | Shift-left testing, IEEE 829-style test plans, QA leadership across parallel products |


📊 Signal


Happy to talk test architecture, AI evaluation and quality engineering.
Explore my tool guides in the Automation Arsenal.
The fastest way to reach me is email or LinkedIn.